When I think about networking in this lab, I start with two paths: reaching the Kubernetes API and moving traffic between workloads. They meet in the same cluster, but they have different responsibilities. kube-vip gives administrators and nodes a stable API endpoint; Cilium provides the pod and service network.
Keeping the API reachable
The kube-vip static pod runs on each of the three control planes. Its configuration enables ARP advertisement and leader election, with one control plane owning the virtual IP at a time. kubeadm points at that address, and the Cilium values use it as the Kubernetes API host on port 6443.
This removes an individual control plane's address from the client configuration. If ownership moves to another eligible node, clients can reconnect through the same endpoint. I do not run separate HAProxy and Keepalived VMs for that purpose in this setup.
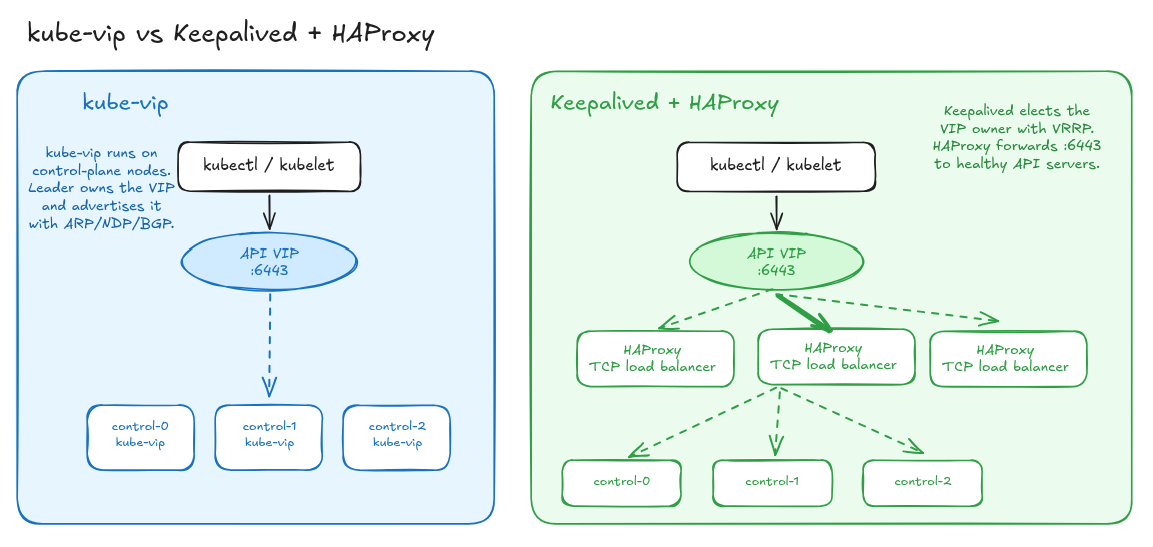
The distinction in this drawing is about where the endpoint machinery lives. A separate HAProxy layer can forward connections to several API servers. My kube-vip configuration instead elects a control plane to own the address. I can inspect that behavior through the static pod manifest, which enables vip_arp, cp_enable, and vip_leaderelection. This configuration does not describe a separate round-robin proxy in front of the API servers.
The limitation is below the network layer. Two etcd members sit on the same Proxmox host. Losing that host leaves the cluster without an etcd majority even if an API address remains reachable. This snippet explains why that failure differs from losing a single VM.
Letting Cilium handle workload traffic
The GitOps values configure Cilium in tunnel mode using VXLAN, with kubeProxyReplacement: true. The live Cilium ConfigMap reported those same settings when checked on September 13, 2026. Hubble relay and UI are enabled as well, giving me a way to inspect network flows through Cilium's tooling.
The important settings sit together in platform/cilium/values.yaml:
k8sServiceHost: 192.168.1.200
k8sServicePort: 6443
kubeProxyReplacement: true
routingMode: tunnel
tunnelProtocol: vxlan
The first two values point Cilium at the same API virtual IP used by kubeadm. The last two keep inter-node pod traffic in a VXLAN overlay on the existing LAN. That makes the boundary between the physical network and the Kubernetes network explicit in the configuration, instead of depending on a pod-network routing setup in the household switch.
There is one Cilium operator replica in the values, another place where this lab favors a small footprint. It would be misleading to infer full component redundancy just because there are three Kubernetes control planes.
The services I inspected were internal ClusterIP services, including Argo CD and Hubble. The running workload list did not contain MetalLB or an NGINX ingress controller. Public service routing for the personal applications in these project notes happens on the cloud VPS through Caddy.
Following metrics across the boundary
The cluster sends metrics outward rather than hosting the whole monitoring stack locally. vmagent reads scrape targets and remote-writes to the VPS over HTTPS with a client certificate. Caddy validates that certificate and routes accepted writes to VictoriaMetrics.
That path ties together several parts of the lab: Cilium carries the traffic, Sealed Secrets supplies the client's credential, Argo CD manages the collection configuration, and the VPS stores the samples. Following a single connection through those components is more useful to me than treating networking as a list of installed tools.
The Argo CD article describes that configuration in more detail. It is also where I track the distinction between a resource being healthy and its configuration agreeing with Git.